Vision-Language Grounded Task-Context-Aware Imitation Learning for Robotic Disassembly
Sep 15, 2026· ,,,,·
0 min read
Jeon Ho Kang
Igal Tamarkin
Ethan Niu
Ian Novales
Satyandra K. Gupta
Abstract
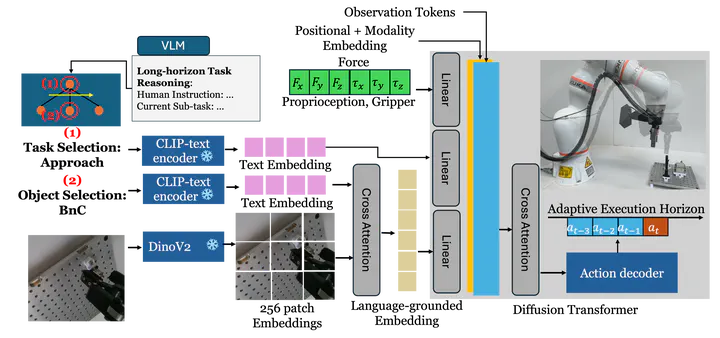
This framework combines hierarchical task selection with task-context-aware imitation learning to ground language instructions in visual representations for robotic disassembly. It generalizes across connector geometries and assembly configurations without explicit object annotations, improving end-to-end task success by 35 percentage points over baseline diffusion policy and 75 percentage points over the previous task-context-aware baseline.
Type
Publication
IEEE Robotics and Automation Letters, 2026 (accepted for publication)
